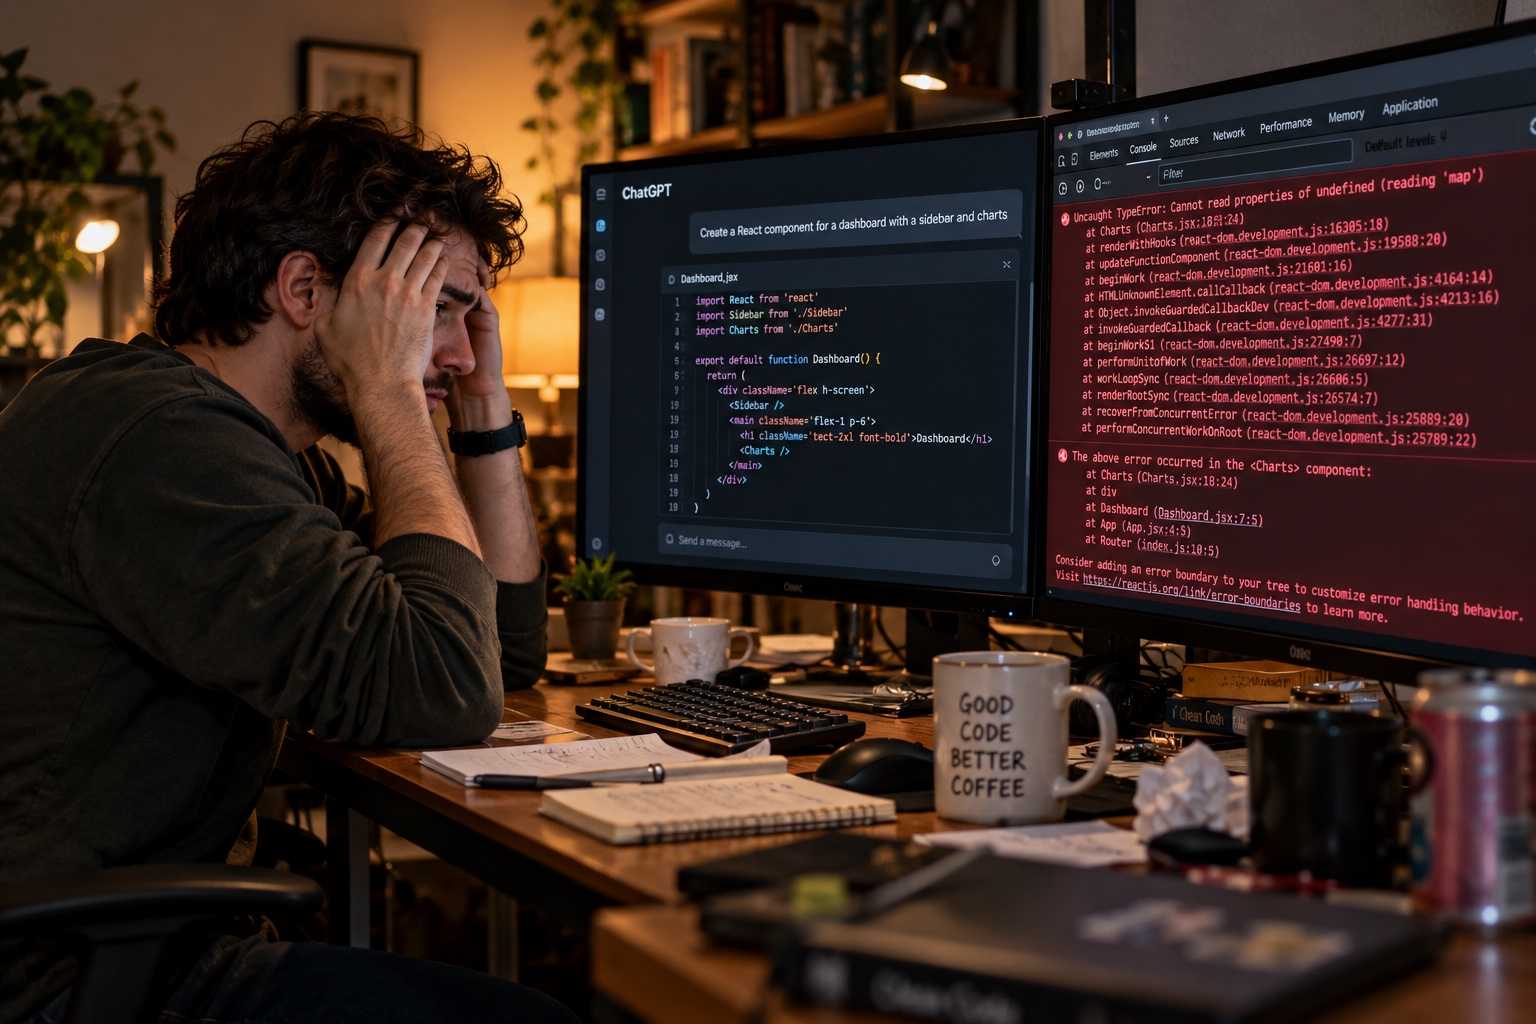
AI can produce a convincing solution with tidy names while hiding an incorrect assumption about authentication, data or failure handling. The useful decision is the one that improves a real task for a real user. Identify the constraint before choosing a tool, metric or redesign.
Why this deserves attention
GitHub’s latest Octoverse report describes rapid growth in AI-related development and TypeScript activity. Those figures describe a platform-wide pattern, not a guarantee that a particular tool will help a small team. The practical question is whether a change improves reliability, accessibility, privacy or the time needed to maintain the product. The review should start with the user problem and the trust boundary rather than the apparent fluency of the code. The relevant measure is the effect on the product and its users, not the novelty of the implementation.
A practical way forward
Ask the author to explain the inputs, expected failures and tests, then run a case that is different from the happy-path example. Set a baseline with one representative task, make a small change and repeat the same check. Share both the result and any trade-off the team observed.
Picture it in a real situation
If an AI adds a file-upload endpoint, review size limits, file type handling and storage permissions before admiring the generated comments. The value of the example lies in making the result observable. If it fails, examine one assumption at a time before replacing the whole workflow.
What to avoid
Avoid approving code because the model also wrote tests; both may share the same mistaken assumption. Test the claim against the version and workload you actually run. A screenshot or benchmark from another product is a clue, not evidence that your users will benefit.
Takeaway
Pick one measurable improvement, test it with a representative user path and document the trade-off.
Sources and further reading: GitHub Octoverse 2025; MDN Web Docs.